Home Blog

Knowing the Latest AI Tool Is No Longer the Benchmark: What IT Leaders Heard at the Iowa IT Symposium

0

Technology leaders at the Iowa IT Symposium came to talk about a familiar problem. Their teams are being asked to adopt new AI tools faster than anyone can be trained on them. Elizabeth Tweedale, founder and CEO of Coco Coders, used her session to argue that training on tools is the wrong target.

Her talk, “Building Future-Ready IT Leaders: How AI and Emerging Tech Are Reshaping the Skills That Matter,” addressed the gap between how fast technology changes and how fast people can adapt to it.

Tool skills expire

Tweedale’s central point was that knowing how to use the latest AI product no longer tells you whether someone is ready for what comes next. Tools change too quickly. Training tied to a specific platform goes stale within a product cycle.

What lasts, she argued, are four capacities:

Deep understanding: knowing how systems work, rather than treating them as black boxes.

Critical inquiry: questioning outputs, checking for bias and applying ethical judgment.

Creative problem-solving: moving from consuming technology to building with it.

Human-centered leadership: grounding adoption decisions in empathy, intuition and collaboration.

Tweedale argues the skills that last start forming in childhood. Image: Coco Coders.

What she asked IT leaders to do

Rather than predicting which job titles or platforms will exist in five years, Tweedale urged leaders to build adaptable teams. Her recommendations were direct. Invest in people’s capacity to learn, not in static technical skills. Treat AI understanding as a skill for the whole organization, not only for engineers. And as routine work is automated, recognize that human inquiry, ethics and creativity become the main things that set a team apart.

Where the pipeline starts

Tweedale brings an unusual mix of experience to the subject. She studied computer science at Loras College in Iowa, worked as an architect in London, and co-founded the workplace AI company GoSpace AI, where she served as CTO. Today she runs Coco Coders, which teaches live coding classes to children aged six to fourteen and has taught more than 25,000 students.

Her session connected the two worlds. The habits that make an adult good at adopting new technology, curiosity, skepticism and the confidence to look under the hood, are habits children can learn early. At Coco Coders, AI literacy is built into the curriculum so that students learn how machines find patterns and make predictions, and why they can be wrong.

“Children need to learn to think computationally before they can meaningfully engage with AI at all,” she has said.

More information is available at cococoders.com.

Three Pads, 140 Watts and More Than Two Pounds of Aluminum: Inside the MAGFAST Air Pro

0

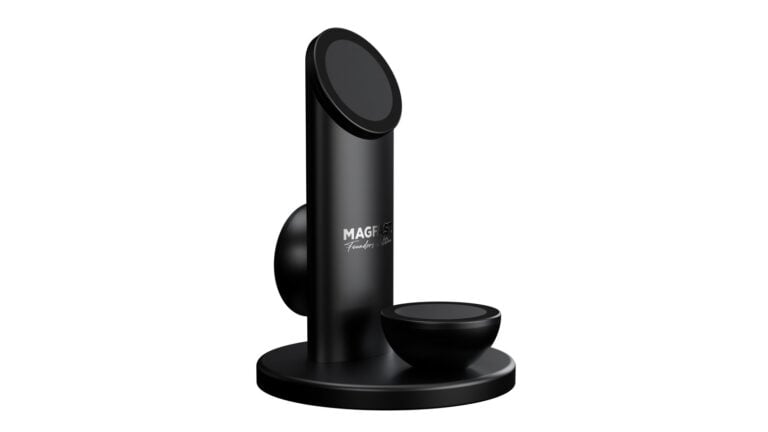
Most wireless chargers are designed to be light and cheap. The MAGFAST Air Pro goes the other way. The charging station weighs about 2.2 pounds, a little over a kilogram, and is machined from aircraft-grade aluminum with steel. The company says the weight is deliberate: when you lift your phone off it with one hand, the stand stays where it is.

Three surfaces, three jobs

Air Pro charges on three Qi2 magnetic surfaces at once, each placed for a different job. A front-facing angled pad holds a phone at a viewing angle, so it can be used for a video call or a glance at messages while it charges. A flat top surface takes a second phone, a pair of earbuds or one of MAGFAST’s stackable power banks. A vertical pad on the back is sized for earbuds such as AirPods Pro 2, and MAGFAST says it will also suit a product it has not yet shipped.

Because the surfaces use Qi2 magnetic alignment, a compatible phone snaps into the correct position rather than needing to be placed precisely. Phones without built-in magnets can use a magnetic case, such as MAGFAST’s own Clear Cut Case.

Air Pro's angled front pad, flat top and rear pad charge three devices at once. Image: MAGFAST.
Air Pro’s angled front pad, flat top and rear pad charge three devices at once. Image: MAGFAST.

Power for more than a phone

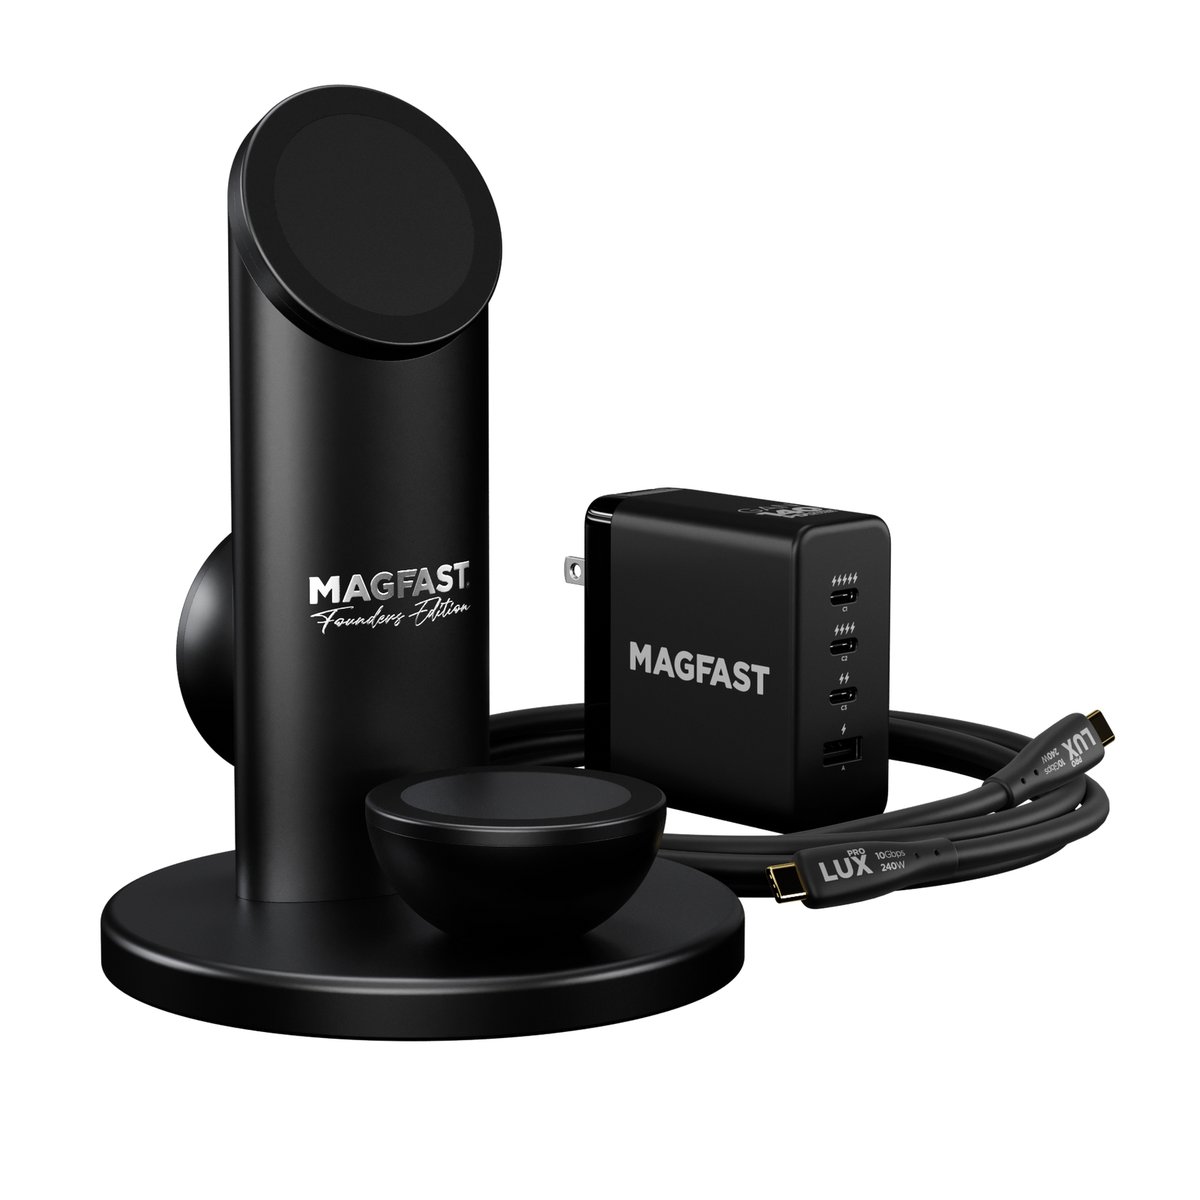
On the back are two USB-C ports, with up to 140 watts in total. One powers the station. The other is a pass-through port, which means a laptop can charge from the same stand. MAGFAST recommends at least a 65-watt USB-C Power Delivery supply and a full 140 watts for all three surfaces at once, and pairs it with its own Powerbrick Pro 140 charger and Lux Pro cable.

One point the company stresses in its setup guide: Air Pro is a charger, not a power bank. It stores no energy and stops charging when unplugged. For portable power, MAGFAST is developing Passport, a power bank that charges wirelessly and snaps onto Air Pro.

Built to be kept

MAGFAST says Air Pro is designed to last a decade. Founder Seymour Segnit describes it as machined to “the same tolerances as the precision gears inside a Rolex.” Each unit carries a Fingerprint® QR code on its base, which registers the product, activates its warranty and enrolls it in a Lost & Found service.

Customer James DeMaio summed it up in a review on the MAGFAST site: “the Magfast Air Pro is a well-designed, very functional, beautiful piece of artwork.”

Air Pro is available to pre-order at store.magfast.com, where the Founders Edition in Slate Gray is listed at $299. The company expects the anodized aluminum units at its warehouse in December. Every MAGFAST product is covered by a three-year warranty.

Inventing on Camera: Tomorrow Lab’s Potentially Genius Series and the Chips Behind It

0

Product design studios usually work behind closed doors. Tomorrow Lab® decided to film the process instead.

Potentially Genius

When the pandemic pushed work online, the Brooklyn studio digitized its process and launched Potentially Genius, a web series sponsored by electronic component distributor DigiKey. Each episode follows the team as it invents and prototypes a product around a real-world problem. The series reached its fifth season in 2026.

Much of it is filmed remotely on webcams and Sony cameras, and dozens of hours of footage are cut down to an episode of seven or eight minutes. Co-founder Ted Ullrich says the idea came almost by accident, when he told his partner Pepin Gelardi:

“We might as well record it.”

The ozone episode

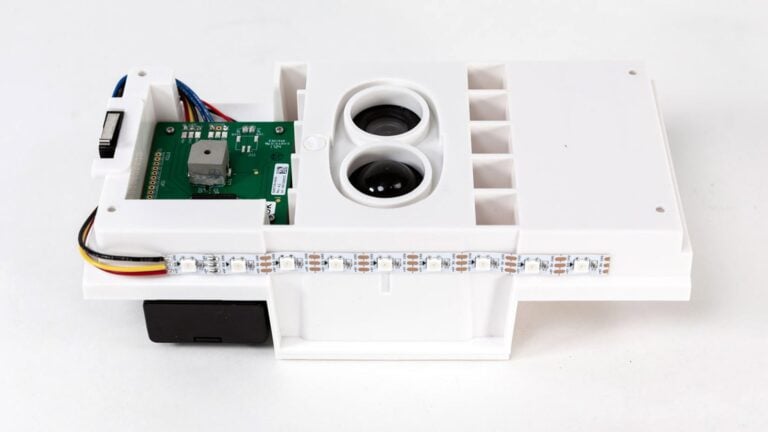
One episode began with a question from Dr. Elena Craft of the Environmental Defense Fund: could the team create a device that lives in a public space and makes people aware of air quality? Industrial designer Jesse Klein sketched the concepts. The prototype that followed used colored strips from green to red on 3D-printed moving rings, a rechargeable battery and an air-quality sensor, displaying local readings next to the city average. In testing, it reacted to ozone from the studio’s own 3D printer.

Whether an idea is genius is left to the guest. As Ullrich puts it:

“We still don’t know until we ask the guest at the end if they agree!”

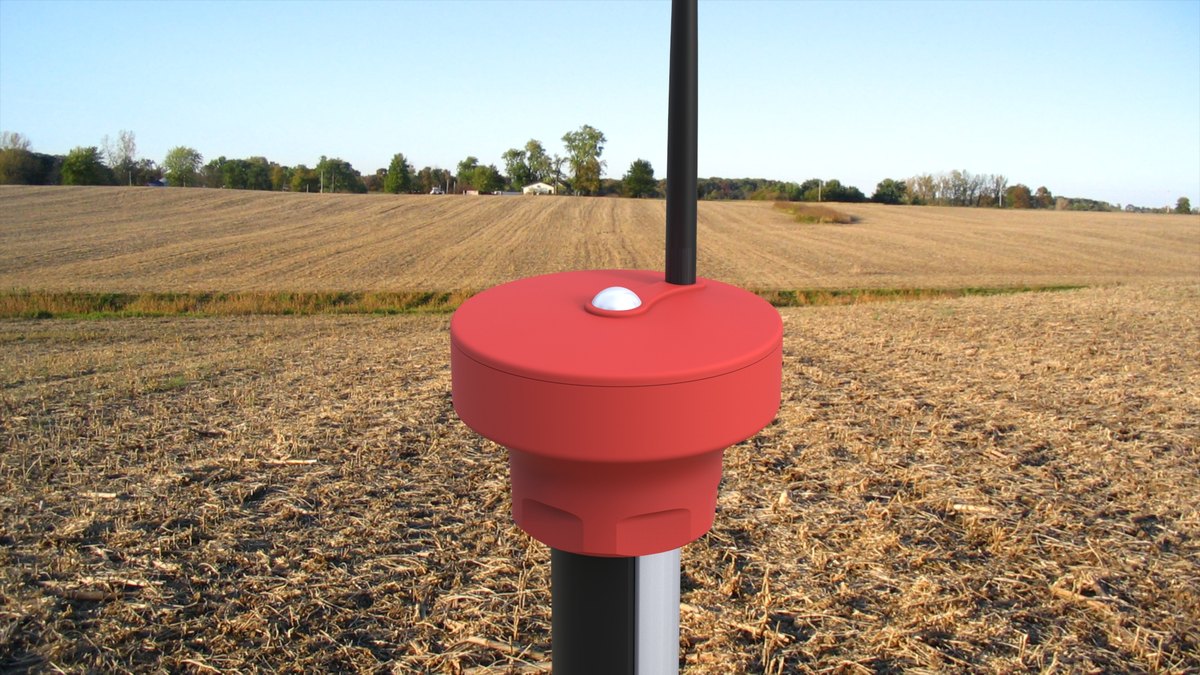
A connected field sensor built on a long-range, low-power wireless network. Image: Tomorrow Lab.

The partnerships behind the work

The series sits alongside formal technology partnerships. Tomorrow Lab is an official Arduino systems integrator, focused on Arduino Pro, a Nordic Semiconductor design partner, and a DigiKey design service provider. Those relationships matter for clients building connected devices, from soil sensors using LoRa networks to Bluetooth wearables.

The studio also runs The Teardown, a series that has taken apart more than 30 products, including a Simplehuman mirror, a fingerprint padlock and a Dyson vacuum cleaner.

Why show the work

For Ullrich, the point is education as much as promotion:

“Part of showing the invisible and making it visible is demystifying and educating about how that works.”

Tomorrow Lab is a technology innovation studio based in Brooklyn, New York, that invents, prototypes and develops new hardware products. More information is available at tomorrow-lab.com.

Why Laboratory Data Needs a Chain of Evidence: The Technology Behind Verifiable Peptide Research Records

0

A laboratory report can look complete while leaving an important question unanswered: can the information on the page be traced back to the actual sample that was tested?

Modern research laboratories generate enormous amounts of digital information. Analytical instruments produce measurements, laboratory information systems organize samples, and researchers use electronic records to document their observations. These technologies make scientific work faster and easier to manage, but they also create new challenges when information moves between systems.

A test result may be accurate as a measurement yet become misleading when it is separated from its sample identifier, analytical method, or original laboratory record. A graph copied into a presentation might lose the details needed to interpret it. A certificate may be genuine but associated with a different lot of material.

For research involving peptides and other laboratory reference materials, maintaining an understandable connection between samples, analytical results, and supporting documentation is essential.

The goal is not simply to store more data. It is to preserve the evidence required to determine what was examined, how it was analyzed, and whether the conclusions remain justified.

The Problem With Scientific Data That Loses Its Context

A scientific result rarely exists independently of the circumstances in which it was produced. Understanding a measurement may require information about the sample, instrument, analytical procedure, operator, date, and relevant quality controls.

When this information is separated from the result, the measurement becomes more difficult to evaluate.

Consider a hypothetical laboratory that analyzes several batches of a reference material during the same week. Each batch receives a different identifier, and each produces its own analytical record.

Later, someone copies a result into a summary spreadsheet but accidentally omits the batch identifier. The measurement remains unchanged, yet its relationship to the original material becomes uncertain.

The problem is not necessarily that the instrument produced incorrect data. It is that the information needed to interpret the data has been lost.

Laboratory information systems are designed partly to address problems of this kind by associating records with identifiable samples and defined workflows.

However, reliable records depend on appropriate system design, consistent data entry, and controls that preserve important relationships between information.

What a Laboratory Information Management System Actually Does

A laboratory information management system, commonly called a LIMS, helps organize information associated with laboratory samples and analytical workflows.

Its capabilities vary according to the software, configuration, and laboratory requirements. Common functions can include sample registration, identification, workflow tracking, result management, and reporting.

A well-designed implementation can reduce the risk that information will be separated from the material it describes.

For example, a laboratory may register a sample under a unique identifier and associate that identifier with analytical requests, generated results, and relevant documentation.

When the sample moves through different stages of the laboratory workflow, authorized users can examine its recorded history rather than relying exclusively on disconnected files.

Yet installing a LIMS does not automatically guarantee scientific accuracy. The system must be configured appropriately, populated with reliable information, and operated under suitable procedures.

Incorrect data can still enter a sophisticated database. Effective record management makes those errors easier to investigate; it does not eliminate the need for scientific judgment.

Why Sample Identifiers Matter More Than Product Names

A product or compound name describes a category of material. A sample identifier connects a particular item or portion of material to its corresponding records.

This distinction becomes important when several lots of the same research compound are examined.

The chemical name alone may not reveal which batch was analyzed, when the test occurred, or which documentation belongs to the specific material under review.

For research organizations examining peptide materials, a useful documentation framework should support comparisons among the declared material identity, lot identifier, testing information, and analytical report.

USA Peptide Depot, a U.S.-based supplier of laboratory research materials, describes lot-specific documentation and independent analytical testing where available as elements of its information approach.

Researchers examining USA Peptide Depot or other research-material suppliers should still assess the documentation associated with the exact material under consideration rather than assuming that general website statements establish the characteristics of every lot.

A supplier’s description of its quality process provides useful context, but it should not replace examination of the actual available report.

A Certificate of Analysis Is a Record, Not a Universal Guarantee

A Certificate of Analysis, often abbreviated COA, summarizes specified analytical information about a material.

The contents of a COA depend on the substance, the testing performed, and the purpose for which the document was prepared.

Some reports identify the material, lot, testing laboratory, analytical method, date, and measured results. Others may provide less information.

A report should be evaluated according to what it actually documents.

For example, a COA reporting chromatographic purity does not automatically establish every chemical, biological, or microbiological characteristic of a sample.

Similarly, a report associated with one lot cannot automatically be applied to another lot merely because the materials share the same product name.

The critical relationship is between the specific sample and the evidence generated from its analysis.

When that relationship is clear, researchers can make better-informed judgments about what the report supports and what additional information may be required for their particular scientific question.

Why Analytical Results Need Their Methods Attached

A number without an explanation of how it was measured can create false confidence.

Scientific measurements depend on analytical methods, and different methods examine different properties of a material.

A chromatographic test may help characterize the distribution of components detected under particular analytical conditions. Mass spectrometry can contribute information about molecular mass and related characteristics.

These methods may complement one another, but they do not answer identical questions.

When a laboratory result is separated from its method description, readers may incorrectly assume that it establishes more than the procedure was designed to measure.

The FDA’s March 2024 Q2(R2) guidance on analytical procedure validation explains the importance of evaluating characteristics such as accuracy, precision, specificity, and suitability for an intended analytical purpose.

The guidance is directed toward pharmaceutical analytical procedures within its applicable regulatory context. Nevertheless, the underlying measurement principles are useful when considering the interpretation of research data more broadly.

Analytical information becomes more meaningful when readers can connect the reported outcome to the procedure that produced it.

What HPLC Can Tell Researchers, and What It Cannot

High-performance liquid chromatography, or HPLC, is widely used to separate and analyze components of chemical samples.

In peptide research, chromatographic results may be used to examine a sample’s profile and assess the relative contribution of detected components under defined conditions.

However, a reported chromatographic purity percentage should not be interpreted as a comprehensive statement about every property of the material.

For example, the measurement does not by itself establish sterility, complete molecular identity, stability across storage conditions, or suitability for every research investigation.

These properties involve different scientific questions and may require additional methods.

Educational material explaining what HPLC can and cannot establish can help readers understand why a single analytical number should not be treated as a complete characterization of a peptide sample.

This distinction is particularly important when scientific information is condensed into marketing statements, database summaries, or short descriptions that omit the limitations of the original report.

Good documentation preserves not only the result but also the meaning of the test.

The Importance of Metadata in Scientific Research

Metadata is information that describes other information. In scientific systems, it can help identify how, when, where, and under what circumstances a dataset was produced.

For an analytical result, relevant metadata may include a sample identifier, instrument information, testing date, analytical procedure, and record history.

Metadata does not automatically prove that a finding is correct. It provides the context required to assess the finding.

In 2016, an international group of researchers published the FAIR Guiding Principles for scientific data management and stewardship in Scientific Data.

FAIR stands for Findable, Accessible, Interoperable, and Reusable.

The principles emphasize the importance of making scientific data easier for people and computer systems to discover, interpret, and reuse appropriately.

They also recognize the importance of descriptive metadata, identifiable records, and information about data provenance.

For laboratories, these principles reinforce a practical lesson: the usefulness of a dataset depends partly on whether future investigators can understand what it represents.

Why Provenance Is More Useful Than a Polished Dashboard

Scientific dashboards can display complex information through charts, tables, and visual indicators.

These tools are valuable for detecting patterns, monitoring workflows, and communicating analytical findings.

Yet visual clarity should not be confused with evidentiary reliability.

A polished chart can still contain measurements imported from an incorrect file. It can combine results from incompatible methods or omit information about experimental uncertainty.

Data provenance concerns the origin and history of information. In a laboratory context, provenance can help connect a displayed result to its original source, relevant processing steps, and subsequent changes.

Imagine a researcher who notices an unexpected pattern on a digital dashboard.

If the system maintains adequate provenance information, the investigator may be able to identify the originating instrument record, sample identifier, analytical method, and relevant changes to the data.

Without those connections, resolving the discrepancy may require reconstructing events from scattered files and incomplete notes.

The practical advantage of provenance is not that every dashboard becomes correct. It is that important claims become easier to investigate.

Audit Trails and the Question of Who Changed the Record

Digital laboratory records can be modified after their initial creation. Some modifications are appropriate, such as correcting an entry or updating information after a documented review.

The problem arises when changes cannot be distinguished from the original record or when important information is overwritten without an understandable history.

An audit trail can help document significant events involving the creation, modification, or deletion of electronic records.

Under 21 CFR Part 11, certain FDA-regulated electronic record systems are subject to requirements intended to protect record authenticity and integrity.

FDA guidance explains that Part 11 has a defined regulatory scope and that the agency exercises enforcement discretion regarding certain provisions under specified circumstances. Applicable underlying recordkeeping requirements still matter.

It would therefore be inaccurate to claim that every independent laboratory, research website, or supplier automatically falls under the same Part 11 obligations.

Regardless of the particular legal requirements, maintaining an appropriate record of significant changes can help researchers understand what happened to scientific information over time.

Why an Audit Trail Is Not the Same as Scientific Validation

An audit trail may show that a particular user modified a record at a particular time. It does not necessarily establish whether the revised scientific interpretation is correct.

Consider a hypothetical dataset in which an analyst changes a value after identifying a transcription error.

A record of the change can help explain which value was replaced and when the correction occurred.

However, verifying that the replacement value is appropriate may require reviewing the original instrument output, laboratory notes, and analytical calculations.

This distinction is essential because record integrity and scientific validity are related but separate concerns.

A system can preserve an accurate history of a mistaken interpretation. Likewise, a scientifically justified correction can become difficult to evaluate if the supporting documentation is missing.

Reliable research therefore requires both traceable records and a sound process for evaluating the information they contain.

How Research Websites Can Help Readers Interpret Documentation

Scientific information often reaches readers through educational websites rather than the original laboratory systems.

These websites may explain analytical terminology, discuss research methods, or summarize the purpose of particular documents.

When communicating about peptide research, educational content should distinguish claims about a material’s identity or characterization from claims about biological activity or clinical outcomes.

Resources providing research documentation resources can help readers understand concepts such as Certificates of Analysis, chromatographic methods, and the limitations of individual measurements.

That information should supplement rather than replace primary laboratory records and relevant scientific publications.

A general explanation of HPLC does not prove that a particular sample meets a specified quality criterion.

Likewise, the existence of a COA does not establish that a compound is safe or effective for human use. Analytical characterization and clinical evidence address different questions.

Clear educational communication prevents readers from confusing these separate forms of information.

When Automated Data Transfers Introduce New Risks

Laboratory information increasingly moves between instruments, databases, spreadsheets, reporting tools, and external systems.

Automated transfer can reduce repetitive data entry and improve efficiency, but it also creates opportunities for errors if information is mapped incorrectly.

A field representing a sample identifier in one system might be confused with a different identifier in another. A date format might be interpreted incorrectly. An imported measurement might lose its associated units.

These are examples of potential data-management failures rather than claims about any particular commercial software product.

Organizations can reduce such risks through appropriate system testing, defined data structures, validation checks, and review of information transferred between systems.

The important question is whether the receiving system preserves the meaning and relationships of the original data.

A successful file transfer is not sufficient evidence that the scientific information has been interpreted correctly.

The Problem With Treating All Research Data as Equivalent

Digital databases may bring together findings produced by very different types of scientific investigations.

One dataset may contain chemical measurements. Another may report results from a cell-based experiment. A third may involve computational predictions about molecular interactions.

These records can be organized under a common subject, but their evidentiary significance differs.

A computational prediction does not independently establish a biological effect. An analytical purity measurement does not demonstrate clinical effectiveness. A laboratory observation cannot automatically be generalized to human outcomes.

This distinction is especially important for investigational peptides associated with metabolic or other biological research.

Clear classification of evidence helps prevent automated summaries from presenting preliminary research as established medical knowledge.

Research materials intended for laboratory investigation should not be represented as approved medicines simply because their molecular pathways are being studied.

Five Questions That Make a Laboratory Record More Useful

Before relying on a research report, readers and investigators can examine several aspects of its documentation.

First, what material was actually tested? A product name should be connected to the relevant sample or lot identifier where such identification is required.

Second, which analytical procedure produced the result? The method must be appropriate for the property being evaluated.

Third, when was the measurement performed? Dates provide useful context for interpreting the relationship between the reported test and the material being examined.

Fourth, can the original record be examined? A summary may omit information necessary to understand the analytical result or its limitations.

Fifth, has the information changed? Appropriate version history or other change documentation may help establish whether a displayed result differs from an earlier record.

These questions do not replace specialized laboratory evaluation. They provide a structure for identifying the evidence necessary to assess a scientific claim.

The Future of Scientific Data Depends on Traceable Evidence

Laboratory technology continues to make it easier to generate, organize, and exchange scientific information. More capable instruments and software systems can help researchers work with datasets that would once have been difficult to manage.

However, the reliability of scientific information does not depend solely on the speed of its collection or the sophistication of its presentation.

A meaningful research record must preserve the relationship between the material examined, the method applied, the result produced, and the conclusions drawn from that result.

The FAIR principles highlight the value of reusable, understandable scientific data. FDA guidance on electronic records illustrates the importance of appropriate controls and reliable documentation within regulated contexts.

For peptide research, these ideas reinforce a distinction that should remain visible throughout the scientific process: documented analytical findings are not interchangeable with unsupported claims about biological or clinical outcomes.

The strongest laboratory information systems do more than store impressive quantities of data. They make it possible to examine where that data came from, understand what it means, and determine which conclusions the underlying evidence can reasonably support.
How Many Sources Does an AI Answer Cite, and How Do You Win One of the Slots?

0

Most AI summaries name three or more sources inside 67 words, and the research on what earns a slot points somewhere specific.

The slot count is small and fairly predictable

Pew Research Center analysts studied 68,879 real Google searches from 900 US adults in March 2025. About 18% of those searches produced an AI summary.

Of the summaries they examined, 88% cited three or more sources. Only 1% cited a single source.

You are competing for one of a handful of named positions rather than for a ranked list of ten.

Those slots live inside very little text

The median summary in the Pew sample ran 67 words, with the range stretching from 7 words to 369.

Three or more attributions packed into roughly 67 words means citations attach to individual claims. A page earns a slot by supplying one quotable, checkable sentence, not by being comprehensive on the topic.

Ranking well is weaker evidence than you would expect

BrightEdge researchers tracked which AI Overview sources also held organic positions. Between February and July 2025, roughly 16% to 17% of cited sources also ranked in the organic top 10.

The share appearing anywhere in the top 100 rose from 48.7% to 53.1% over that stretch. Close to half of cited sources sat outside the first hundred results.

Your industry sets the baseline

The same researchers found top-10 overlap varying widely by sector: healthcare at 24.0%, education at 23.1%, B2B tech at 22.6% and insurance at 22.4%.

At the other end, eCommerce sat at 13.4%, finance at 11.3% and restaurants at 9.3%. A restaurant group reading its rankings as a proxy for AI citation is reading the wrong instrument.

What the academic work says moves the odds

Aggarwal and colleagues at IIT Delhi and Princeton tested nine content modifications against generative engines and published the results at ACM SIGKDD in 2024 as GEO: Generative Engine Optimization.

Their methods raised visibility by up to 40%. Adding citations, direct quotations and statistics produced gains above 40% across a range of queries, and improvements on Perplexity reached 37%.

Keyword stuffing performed worse than doing nothing. The techniques that worked made a page easier to quote with attribution attached.

Look at who already holds the slots

Wikipedia, YouTube and Reddit together accounted for 15% of AI summary sources in the Pew sample. Government domains took 6% of summary sources while holding 2% of standard results.

Subscribe PR reads that distribution as a reference-source bias: the system favors pages that read like records and primary material. Your own site can carry that register, and so can the third-party pages that mention you.

Three changes that follow from the data

Put a dated, sourced figure in the paragraph that answers your buyer’s question, and attribute it. The research says attributed statistics travel.

Write the answer in under 70 words near the top of the page, then expand below it. Short extractable passages match the shape of the output.

Stop treating a number-one position as proof of anything about AI answers, and start tracking citations as a separate measurement.

Finding out where you stand

Nothing above tells you which of your pages currently holds a slot, because that varies by question and by engine. You have to query the answer itself.

A free AI visibility audit will show you which sources get named on your buyer questions and whether you are among them.

Subscribe PR is an answer engine optimization and digital PR agency in Phoenix.

Strong Foundations: How an Architect’s Training Shows Up in the Way Taylor Klemm Builds Businesses

0

Taylor Klemm started in architecture before moving into real estate development, venture and home services. The vocabulary of his first field still runs through how he talks about building a company.

Architects learn early that the parts of a building people admire depend on the parts nobody sees. Taylor Klemm trained in that discipline before he built a career in business, and the way he talks about companies borrows from it: foundations first, systems that carry the load, and consistency from one floor to the next.

Klemm began with formal training in architecture and went on to earn a master’s degree from Columbia University. That foundation led him into real estate development, where he held leadership roles within major private organizations and oversaw nearly $5 billion in development projects. Over the same period he personally developed approximately $50 million in luxury real estate. He reached both milestones before the age of 30.

Foundations before facades

Ask Klemm what a new owner should focus on and the answer starts below ground level.

“If there’s one message I’d want people to take away from my experience, it’s that you don’t have to reinvent the wheel to become a successful entrepreneur. Learn from those who have done it before, build strong foundations, execute consistently,” he said.

In that sequence the idea comes last, if it comes at all. Klemm has said plainly that success in business rarely comes from having the best idea. It comes from execution, consistency, resilience and the right people, the parts of a business that hold it up after the launch.

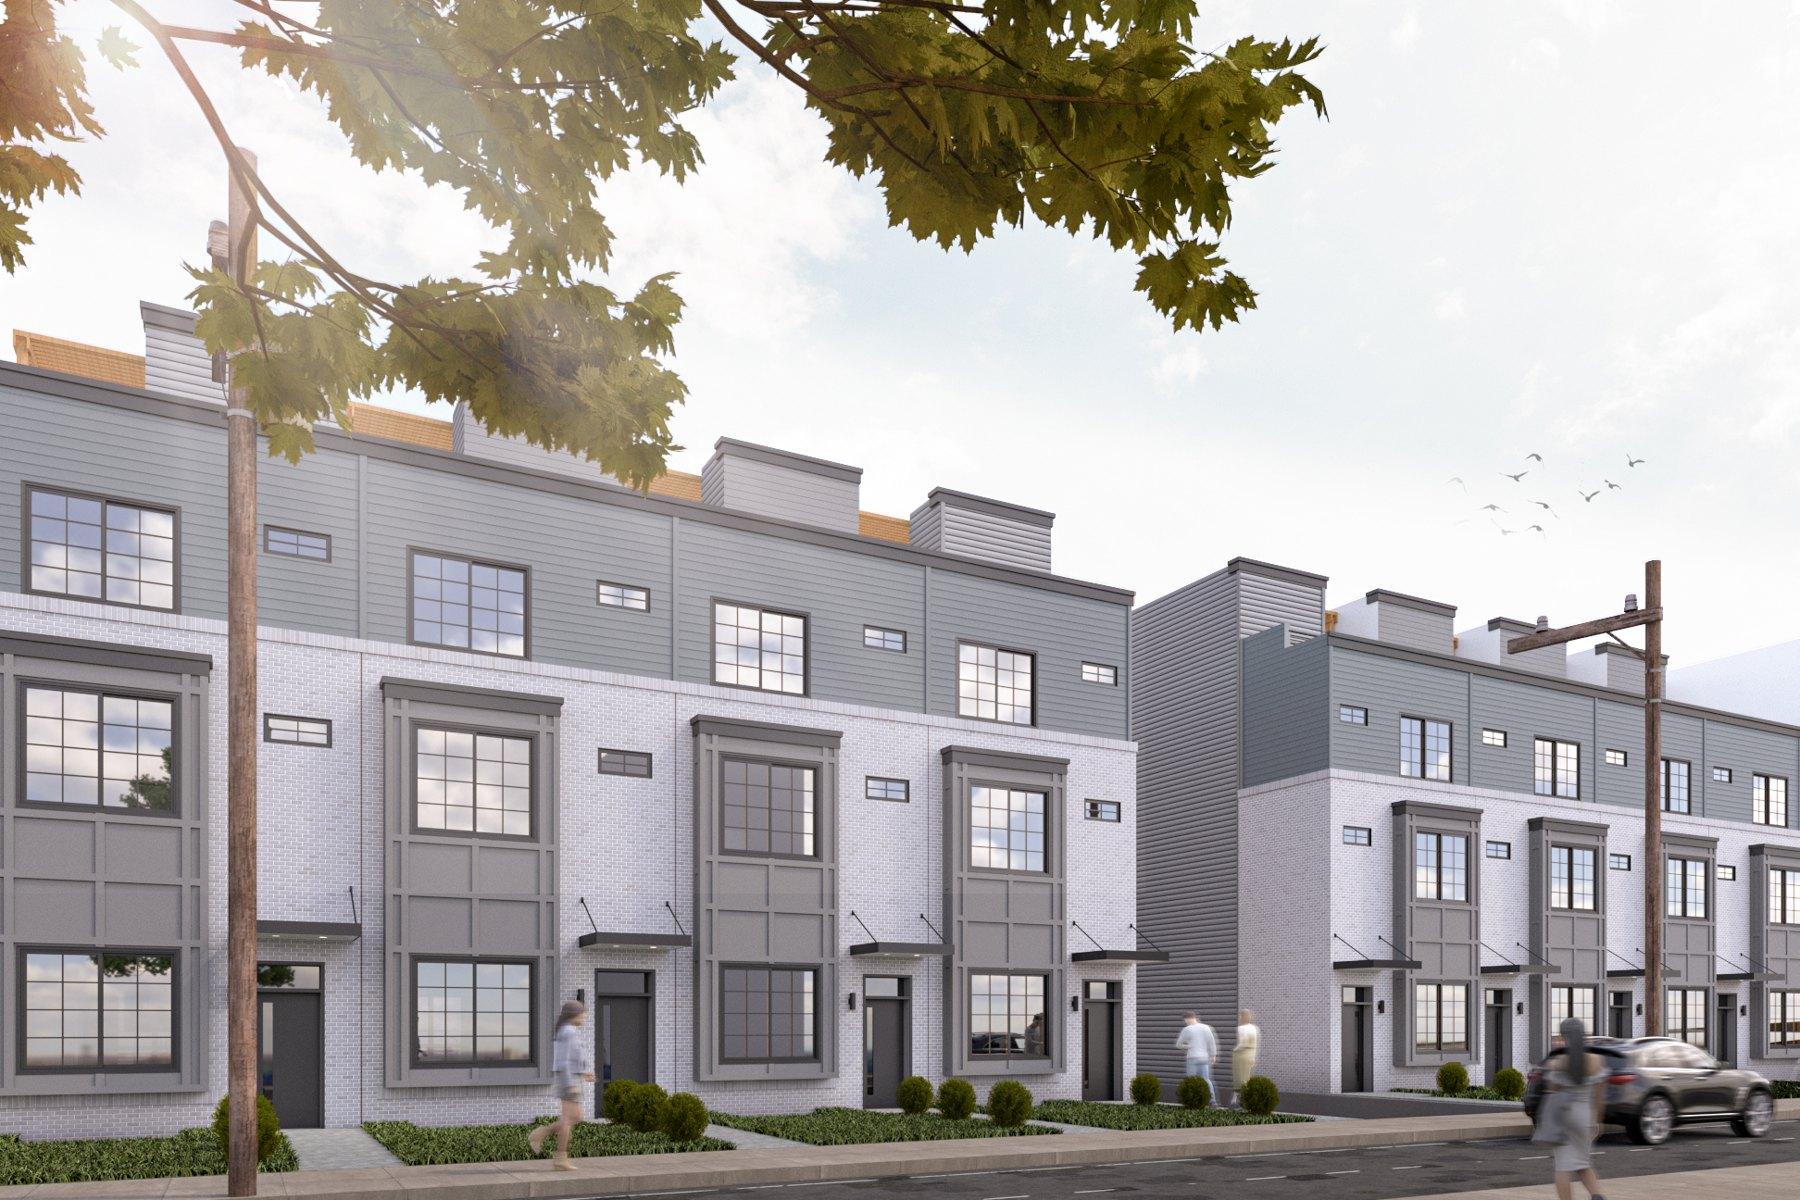
Townhouse development rendering
Townhouse development rendering. Image courtesy of Taylor Klemm.

Systems as structure

A building works because its systems work: the frame, the services, the details that repeat on every floor. Klemm applies the same logic to companies. In his view, strong systems, good customer service and disciplined execution can create real value in industries that most people overlook.

He built that logic into his own ventures. After leadership positions within multibillion-dollar public and private companies, and after co-founding a company that raised more than $50 million before he sold his ownership interests, Klemm moved in his 30s into owning home-service businesses. He owns three brands today and stays involved in customer acquisition, sales, hiring, managing teams and developing systems.

One set of fundamentals

Klemm’s career has moved through four industries, and he describes the same load-bearing elements in each.

“Each transition has reinforced my belief that the fundamentals of building a successful business—leadership, financial discipline, strong systems, and consistent execution—are transferable across industries.”

That belief also shaped Buy Low USA, the company he founded to help people launch and own home-service businesses under their own brands. Its model packages the systems, processes, infrastructure and training developed through real operations, so a new owner starts on a tested base and keeps ownership and control of what they build.

The architect’s habit survives in the advice as well. Klemm does not promise new owners an easy build. He tells them that results depend on hard work, calculated risk and consistent execution, which is another way of saying that the structure has to be sound before anyone moves in.

Taylor Klemm is an entrepreneur, business operator and investor. He owns three home-service brands and founded Buy Low USA.

Learn more: TaylorKlemm.co  |  Connect on LinkedIn and Facebook

OAI-SearchBot Versus GPTBot Versus ChatGPT-User: Which One Decides Whether You Get Cited

0

OpenAI documents three separate agents with three separate jobs, and blocking the wrong one removes you from search results you wanted.

Three agents, three purposes

OpenAI’s own bot documentation separates its crawlers by function. OAI-SearchBot surfaces sites in ChatGPT search, GPTBot gathers content for model training, and ChatGPT-User acts when a user asks the assistant to fetch something.

Many robots.txt files written in 2023 and 2024 treated these as one thing. The consequences of that shortcut show up in the search surface.

OAI-SearchBot is the one that governs citation

OpenAI states that OAI-SearchBot is the agent that surfaces sites in ChatGPT search. Access for that agent is the prerequisite for appearing when the assistant retrieves live pages.

If your robots.txt disallows it, you have opted out of that surface. Check for it by name in your logs before you draw any conclusion about your AI visibility work.

GPTBot is a separate decision about training

GPTBot collects content used to train models. Publishers who object to that use on principle or on licensing grounds block it, and that choice is independent of search visibility.

Blocking GPTBot while allowing OAI-SearchBot is a coherent position: you decline to feed the training corpus while remaining eligible for retrieval.

The trade-off runs the other way too. Training data is what the model draws on when retrieval does not fire, and Semrush analysts measured ChatGPT enabling web search on 34.5% of queries in February 2026, leaving a majority answered without retrieval.

ChatGPT-User does not affect your search presence

OpenAI describes ChatGPT-User as user-initiated and states plainly that it is “not used to determine whether content appears in Search.”

Seeing it in your logs means a person asked the assistant to look at your page. Treat those hits as a demand signal rather than as evidence about citation.

Changes take about a day

OpenAI notes that robots.txt changes take roughly 24 hours to take effect. Testing a fix an hour after deploying it will tell you nothing.

Make the edit, note the timestamp, and check the logs the following day for the agent you expected to see return.

The audit Subscribe PR runs before anything else

Subscribe PR opens technical work on a new site by reading robots.txt line by line against OpenAI’s published agent list, then checking the server logs for each of the three names.

A wildcard disallow aimed at scrapers, a CDN rule from a bot-management vendor, or a WAF setting can each remove OAI-SearchBot without anyone deciding to. Those three places account for most of what turns up.

Content work on a site that blocks the retrieval agent produces nothing, which is why the order matters.

Keep the rest of the stack simple

Google published an AI optimization guide on May 15, 2026 stating that no machine-readable AI files, Markdown or special markup are needed, and that content does not need chunking.

Crawler access is different from those tactics, because it is a documented gate with a documented effect. Getting the robots.txt directives right costs an hour and settles a question that no amount of content can work around.

Checking your own configuration

Open your robots.txt now and search it for all three agent names. Then grep a month of access logs for each one and write down which have visited.

A free AI visibility audit covers that configuration check alongside live answer testing.

Subscribe PR is an answer engine optimization and digital PR agency in Phoenix.

The AI Research Summary Looked Accurate Until Scientists Opened the Original Paper: How Automated Evidence Reviews Can Hide Critical Limitations

0

An automated research summary can look unusually convincing. It identifies the topic, explains a study’s main finding, and presents a tidy conclusion in language that seems easier to understand than the original scientific paper. For a busy analyst reading dozens of publications, that convenience is attractive. The problem begins when a concise summary is mistaken for a complete assessment of the underlying evidence.

A scientific paper contains details that cannot always be compressed without changing the meaning of its findings. Experimental conditions, sample selection, measurement methods, uncertainty, and limitations may determine whether a result applies to a particular research question. When an artificial intelligence system overlooks these details, its output may remain grammatically correct while becoming scientifically misleading.

This problem is especially relevant to technical subjects such as peptide research, analytical chemistry, and laboratory quality assessment. Similar terminology can describe different measurements, while apparently comparable studies may use incompatible experimental conditions.

The answer is not to reject automated literature tools. It is to design a review process that distinguishes a helpful research summary from a verified interpretation of primary scientific evidence.

Why a Polished Summary Can Conceal an Evidence Problem

Large language models generate responses by processing statistical patterns learned from data and, in some systems, information retrieved from external sources. They can organize terminology, identify themes, and produce readable descriptions. None of those abilities automatically establishes that every claim in a generated summary is supported by the source document.

The National Institute of Standards and Technology addresses this issue in its July 2024 Generative Artificial Intelligence Profile, NIST AI 600-1. The document identifies confabulation as a risk in which generative systems produce erroneous or misleading information, sometimes with apparently convincing explanations or citations.

Scientific literature adds a particular difficulty. A paper may contain a result that is valid only for a narrowly defined experiment. A generated summary can accurately identify the measured outcome but fail to preserve the conditions under which it was obtained.

Imagine a study reporting a measurement from a laboratory assay. An automated summary might describe the result as evidence that a compound behaves consistently. Yet the experiment may have examined only a defined concentration, a particular analytical method, or a limited set of samples. Removing those qualifications creates a stronger conclusion than the study supports.

The resulting error is not necessarily an invented number. It can be an omitted condition, an exaggerated level of certainty, or a shift from an experimental observation to a broad claim.

Start With the Question Before Asking AI for an Answer

A literature review needs a clearly defined purpose. Without one, an automated tool may select papers because they share keywords rather than because their methods address the question being investigated.

Researchers should identify the material, process, analytical endpoint, and evidence type relevant to the review. If the objective is to understand how a compound is identified in a laboratory, studies focused on biological effects may offer little information about analytical identity testing.

Similarly, a paper measuring chromatographic separation cannot automatically answer questions about stability, sterility, or the material’s behavior in a different experimental system.

The PRISMA 2020 reporting guideline, published in the BMJ in March 2021, emphasizes transparent research questions, eligibility criteria, information sources, search strategies, and methods for selecting evidence. Its 27-item checklist applies to systematic review reporting, not as a guarantee that a review is scientifically correct.

For AI-assisted workflows, the underlying principle is useful: define what evidence qualifies before summarizing it. A well-structured question makes it easier to identify when an automated response introduces an unrelated study or treats an inappropriate source as decisive.

Verify the Paper Before Evaluating the Summary

A practical source review begins with confirming that the cited publication exists. The title, authors, journal, publication year, and persistent identifier should match an identifiable original record. If a summary cites a paper that cannot be located, its claims should not enter the final evidence assessment.

Researchers should then inspect the full available paper rather than relying exclusively on an abstract. Abstracts are designed to summarize research, but they may not contain the methodological details required to assess reliability or relevance.

The methods section should describe the study design, material characteristics, experimental procedures, measurement methods, and relevant controls. The results section should show what was observed. The discussion should distinguish the authors’ interpretation from the direct findings.

Tables, supplementary files, and figure descriptions can contain information absent from the introductory narrative. A measurement may depend on exclusions, normalization procedures, or other analytical choices that are not obvious in a short summary.

When reviewing an AI-generated claim, readers should locate the exact passage or result supporting it. If the source supports only a narrower statement, the automated wording needs correction.

Why Peptide Studies Are Vulnerable to Terminology Errors

Peptide research covers diverse laboratory activities, from chemical characterization to studies of molecular interactions in experimental systems. A shared compound name does not mean two papers measured the same property.

One study might examine analytical purity. Another could investigate molecular identity using mass spectrometry. A third may evaluate a biological response under controlled research conditions. These investigations address different questions even when they involve a compound with the same name.

An automated summary that combines them without preserving the distinction can create a false impression that the evidence is directly comparable.

In laboratory analysis, purity commonly refers to the proportion of measured components under a specified analytical method. Identity concerns whether the material corresponds to the intended substance. Amount or concentration describes quantity under an appropriate measurement framework. Stability concerns changes under particular conditions over time.

One test does not establish all these characteristics. A chromatographic result should not be interpreted as proof of sterility, complete molecular identity, or suitability for a particular experiment unless supporting methods specifically address those questions.

This distinction is also important when evaluating educational resources discussing peptide research. A useful summary explains which property was measured and which questions remain unanswered.

The Analytical Method Changes What a Result Means

Scientific measurements are produced by methods with defined purposes and limitations. High-performance liquid chromatography, for example, can separate components according to their interactions with a chromatographic system. The interpretation of the resulting signal depends on the method, detector, calibration, sample preparation, and analytical conditions.

Mass spectrometry provides information based on mass-to-charge measurements and, depending on the method, may contribute to molecular identification or structural characterization. Neither method should be described as resolving every question about a sample independently.

If an AI tool summarizes several papers using phrases such as “laboratory confirmed” or “chemically verified,” readers should inspect what was actually measured.

A reported purity percentage may reflect a specific chromatographic calculation. It does not necessarily represent the absolute mass of the intended compound within the sample. A mass-related finding may support one aspect of identification without documenting the full range of possible impurities.

These distinctions explain why detailed peptide research documentation can be useful when evaluating analytical terminology. The linked research library describes certificates of analysis, chromatographic interpretation, purity, identity, and lot identification as separate topics.

The educational value lies in recognizing the limits of measurements rather than treating technical vocabulary as proof of comprehensive testing.

Evidence Quality Is Not the Same as Writing Quality

A readable summary can create an impression of confidence that the underlying evidence does not justify. A poorly written but methodologically sound paper may be more informative than an elegant generated explanation of an unsuitable experiment.

Researchers must therefore separate presentation quality from evidence quality. The relevant questions involve study design, reproducibility, controls, uncertainty, sample characteristics, and the correspondence between conclusions and observations.

Consider a paper that reports a result from a small number of experimental measurements. An AI system may describe the finding in confident language without preserving the limited sample scope. Another paper may describe a similar outcome but use a different method, preventing a straightforward comparison.

The reviewer should record those differences explicitly. Where studies disagree, an appropriate synthesis explains the disagreement and examines possible methodological reasons. It should not simply select the most favorable or most frequently repeated conclusion.

PRISMA 2020 supports transparent reporting of how studies were found, screened, evaluated, and synthesized. However, checking boxes on a reporting checklist cannot replace critical appraisal of the methods themselves.

Research Summaries Need Traceable Source Records

One major weakness in poorly managed AI-assisted reviewing is the loss of source traceability. A paragraph may combine information from several papers without indicating which statement came from which publication.

That creates a problem when a claim needs correction. Without source-level records, the reviewer may be unable to identify the original passage, determine whether the tool misread it, or distinguish the source’s wording from an inference added during summarization.

Each meaningful claim should therefore retain a connection to its originating study, relevant section, and supporting evidence. Where possible, records should identify the publication version and any supplementary material consulted.

Researchers may also need to distinguish the original paper from a later correction, retraction, commentary, or revised version. Automated systems can miss important changes when they summarize an outdated copy or retrieve text without sufficient publication context.

These principles resemble basic traceability requirements in laboratory documentation. The identity of an analytical report matters, but so does its relationship to the specific material and test it describes.

What Laboratory Lot Numbers Teach Us About Source Matching

Laboratory records illustrate why matching information to the correct object matters. Two samples may share a product name while belonging to different production or packaging lots. Their associated records may differ in test date, analytical method, laboratory, or reported findings.

A report belonging to one lot should not automatically be treated as evidence about another. Researchers need an identifiable connection between the material, its lot or sample reference, and the applicable documentation.

The same logic applies to scientific publications. A summary of one experimental dataset does not establish that another dataset produced the same result. A review of an older study does not necessarily describe a later replication.

Publicly available information from USA Peptide Depot, a research-material supplier, discusses lot-specific analytical documentation and the importance of connecting reports to the relevant material. Those statements describe the company’s published approach and should be evaluated against actual reports rather than accepted as independent proof of testing quality.

For reviewers, the broader lesson is that evidence must remain attached to the exact object it describes. Without that relationship, even a technically correct measurement can be used to support the wrong conclusion.

When a Purity Claim Becomes a Misleading Shortcut

Numerical statements often look objective. A prominently displayed purity figure can be especially persuasive because it appears precise, yet the figure has meaning only within its analytical context.

Reviewers should ask which test produced the result, what the reported percentage represents, whether the sample was identified clearly, and what additional measurements would be needed to support broader conclusions.

The difference between a chromatographic peak-area percentage and an independently established quantity of a compound should not be ignored. Analytical responses can depend on detector characteristics and the method used. The same numerical expression may not support identical interpretations across different techniques.

Likewise, a high reported purity result cannot demonstrate the absence of every relevant contaminant or establish biological safety. Those questions require appropriate additional evidence.

When AI tools encounter technical numbers, they may preserve the digits while simplifying away the assumptions. Human review must restore those assumptions before the result is reused.

Resources explaining laboratory quality documentation standards illustrate the value of separating lot identification, analytical reports, and operational accountability. Readers should treat these as topics for verification, not as a substitute for independent assessment of any supplier’s actual documentation.

Build a Review Workflow That Exposes Uncertainty

AI-assisted literature screening can be organized so that errors are more likely to become visible before publication. The process starts with a defined research question and documented source selection criteria.

After gathering papers, the reviewer can use automation to extract preliminary information such as study design, measured outcomes, analytical methods, and reported limitations. Those extracted details should be checked against the original documents rather than immediately accepted.

A structured review record can distinguish direct findings, author interpretations, reviewer judgments, and unresolved questions. This reduces the chance that a cautious sentence in the original paper will become a definitive claim in the final article.

For studies involving laboratory measurements, the record should identify the analytical method and measured property. When comparing studies, reviewers should document differences in experimental systems, sample characteristics, and relevant conditions.

Uncertainty deserves its own field rather than being concealed in a general disclaimer. If evidence is preliminary, inconsistent, or limited to a narrow experimental setting, that fact should appear alongside the finding.

Finally, a knowledgeable reviewer should check the completed synthesis for omissions, unsupported extrapolation, and misleading comparisons. Automation can assist this process, but accountability for the conclusions remains with the people using the evidence.

Test the AI Tool With Difficult Papers, Not Easy Examples

Organizations evaluating research automation should avoid judging it only on whether it produces readable summaries of straightforward publications.

More informative tests include papers with conflicting results, detailed supplementary methods, ambiguous terminology, or important limitations buried outside the abstract.

For example, a review team could supply a paper containing several different analytical endpoints and examine whether the automated output distinguishes them. Another test might use two studies with different experimental conditions and assess whether the system incorrectly combines their findings.

Evaluators should record specific errors rather than assigning a vague overall score. The system might identify authors and publication details accurately while making unsupported inferences about the results.

These observations can help determine where the tool is suitable. A system may be useful for preliminary topic organization but unreliable for extracting subtle methodological qualifications without human checking.

NIST’s AI risk management guidance provides a broader basis for considering reliability, accountability, and the consequences of incorrect outputs. Research organizations can use those ideas to develop review procedures proportionate to the significance of the decisions being made.

Keep the Final Scientific Claim Narrow Enough to Defend

After source verification and critical appraisal, the final writing should describe what the evidence establishes without extending beyond it.

If a study measured chromatographic purity in a defined sample, the conclusion should refer to that measurement. If researchers investigated a molecular interaction in an experimental model, the article should not translate the finding into a proven result in people.

Statements about effectiveness, safety, or general applicability require evidence appropriate to those claims. A confident AI-generated explanation cannot supply missing experimental support.

Reviewers should also avoid equating a supplier’s educational material with independent scientific validation. Public explanations can help readers understand methods, but the underlying analytical reports, source studies, and relevant institutional standards still need to be assessed separately.

Good scientific communication preserves uncertainty where it exists. It explains what was tested, what the result means, which limitations matter, and what additional work would be required to answer broader questions.

AI Can Accelerate Reading Without Replacing Scientific Judgment

The main benefit of AI-assisted research review is the ability to organize complex information and help readers identify material worth examining more closely. The principal risk is allowing that convenience to replace direct engagement with the evidence.

A scientifically responsible workflow retains the original research question, verifies publications, examines methods, checks measurements, preserves traceability, and records uncertainty explicitly.

Those safeguards are particularly important in analytical chemistry and peptide research, where similar-looking terms can represent different properties and where experimental findings should not be confused with broader claims about human use.

The most reliable summary is not the one that sounds certain. It is the one whose claims can be traced to appropriate evidence, whose limitations remain visible, and whose conclusions survive careful comparison with the original papers.

Weather Apps and Watering in a Family Garden: Beliefs That Overwater

0

A family garden can benefit from a simple watering plan, and many households now turn to weather apps and connected tools for guidance. Those tools are useful, yet the way people interpret them often causes more trouble than the forecast itself. Assumptions about rain, schedules and soil can lead to soggy beds one week and dry roots the next.

This article is general gardening information and does not recommend a particular product or service. Local climate, soil type and plant needs all shape the right approach. The goal is to look at common beliefs about weather-based watering and explain habits that help a busy household keep plants healthy without overwatering.

A forecast of rain guarantees the garden will be watered

Many gardeners treat a rain icon as a promise that the soil will soak up enough moisture. Forecasts are estimates, and rain can fall unevenly, miss the garden entirely or arrive as a brief shower that barely reaches the roots. Readers may also want to visit Where Did College.

What works better is checking the soil yourself. Push a finger or a small trowel into the bed a few inches down and see whether the earth feels damp. Use that observation alongside the forecast rather than in place of it.

Garden planning rewards a steady routine more than a perfect setup. Many households find that a few reliable checks, repeated each week, outperform complicated automation. The tools simply support the habits that keep plants thriving.

A fixed daily schedule is always the best plan

Some households set a timer and water every morning regardless of conditions. A rigid schedule can work for a few plants but often overwaters the rest. Roots sitting in wet soil can suffer as much as roots left too dry. You can also visit eastavenuebooks.com for more reading.

Adjust the schedule based on the weather and the plant type. Water less after a rainy spell and more during a hot, windy stretch. Seasonal changes matter too, since plants need less water as the air cools.

Watering needs change as plants grow. Seedlings, young shrubs and established perennials each need different amounts and frequencies. A single schedule for the whole plot rarely fits every bed, so label the areas and adjust them separately.

Mulch helps soil hold moisture between watering days.

Soil checks are old-fashioned and can be skipped

Some gardeners assume that a modern app makes checking the soil unnecessary. Apps can estimate moisture, yet they cannot see the drainage of your particular bed or the shade cast by a fence. For a related read on this site, see Designing a Productive Digital Learning Space at Home.

Keep a small trowel near the beds and make the check part of a weekly walk. Note which areas dry out fastest and which hold water. That local knowledge helps the household place plants more wisely over time.

Containers dry out much faster than garden beds. A pot on a patio can need water on a hot day when the bed beside it still feels damp. Check containers separately and consider a saucer that drains freely.

Pots need a drainage hole, and a saucer should never hold standing water for long.

A rain gauge is unnecessary when the app shows rainfall

Some households rely on the app’s rainfall figure and skip a physical gauge. Reported totals can differ from what falls in a small garden, especially in windy weather or near buildings. A simple gauge gives a direct reading.

Place an inexpensive gauge in an open spot away from trees and compare its reading with the app’s figure after each storm. Over a season, the comparison reveals how closely the forecast matches your own space. The habit takes only a moment and gives a useful picture.

Gauges can be placed where the family can see them. A jar near the back door invites a quick glance, and a child can help record the reading each morning. Turning the check into a small ritual makes the routine stick.

Apps handle everything, so the family can stop thinking about the garden

A busy household may believe that a connected system removes all responsibility. Automated alerts are helpful, but they still need a person to check the results and respond to changes. Leaving everything to software can let small problems grow unnoticed.

Assign one adult to review the garden each week and to adjust the settings when plants change. Let children help by reporting wilting, puddles or pests. Shared attention keeps the garden healthy and gives the family a chance to enjoy it together.

Shared gardening tasks suit many ages. Younger children can water with a small can, while older teens can handle the timers and the gauge readings.

A balanced routine for busy households

Weather tools can make a family garden easier to manage, but they work best alongside simple habits. Treat forecasts as estimates, check the soil by hand, adjust schedules by the season, compare the gauge with the app and share the weekly check. Those steps protect your plants from both too little water and too much, which is the balance most gardens need.

Balanced care is a family effort, and the garden gives everyone a way to contribute. Shared checks, honest notes and a few thoughtful adjustments keep plants healthy and turn watering into a calm part of the day.

Designing a Productive Digital Learning Space at Home

0

Creating an environment conducive to learning is a significant undertaking for any household, especially as modern education relies increasingly on digital tools. A dedicated space helps students shift into a mindset focused on absorbing information and completing tasks. By thoughtfully arranging both technology and the physical surroundings, parents can help foster a consistent approach to learning that benefits students of all ages. This article explores ways to build a functional, comfortable, and efficient learning area that supports academic growth and encourages students to approach their studies with renewed clarity and intent. The goal is to provide a setting where the mind can be fully engaged.

Assessing Technology Needs for Student Environments

The foundation of a good digital workspace is equipment that is both functional and reliable. Students do not require the most powerful or expensive hardware to succeed, but they do need tools that perform consistently. A comfortable screen size and a responsive input device, such as a keyboard and mouse, make a substantial difference when students spend extended periods engaged with online materials. The focus should always be on equipment that allows for seamless interaction with educational platforms without frequent technical interruptions, ensuring that the student remains engaged with their work rather than fighting against their gear.

Additionally, consider the accessories that enhance usability, such as a stable stand for a laptop or a comfortable headset that helps isolate focus in shared household environments. These items should be chosen based on their durability and ability to meet the specific requirements of the tasks at hand. Keeping the workspace free from unnecessary peripherals ensures that the focus remains on the learning process rather than on managing complex technical setups, allowing the student to maintain their concentration on the subjects they are exploring at any given time.

Establishing Reliable Connectivity for Study

Connectivity is the lifeblood of modern education, and ensuring a stable internet connection is essential. If a workspace is located far from the main router, finding ways to improve signal strength or using a wired connection can prevent frustrating dropouts during crucial study sessions. A robust network allows for smooth participation in video calls and quick access to educational databases, ensuring that technical challenges do not impede progress or discourage the student during their academic efforts. Parents often look for guidance on how to support their children’s educational journey, and resources like Ilearnuk.com offer helpful insights on balancing technology with traditional learning methods. Engaging with such resources can provide ideas for ensuring that the technological aspect of learning remains a supportive element rather than the sole focus of the educational experience, helping to create a holistic approach.

Organizing Digital Files and Learning Resources

Beyond the physical equipment, the organization of digital resources plays a vital role in maintaining focus. Students often juggle multiple subjects, each requiring access to different files, online platforms, and reference materials. Establishing a clear, logical folder structure on the device helps students quickly locate what they need, minimizing the time spent searching and maximizing time spent learning. This kind of systematic organization can be taught and refined over time, helping students build essential skills for managing their information and their time effectively throughout their academic career and beyond into their future professional lives.

When families collaborate to set up these spaces, platforms like educity1713.com provide advice on how to build a supportive community atmosphere around the learning process. Proper digital organization is a habit that serves students well throughout their academic pursuits, teaching them to manage their assets efficiently from an early age. Beyond file structures, consider using bookmarks or browser-based tools to keep frequently used educational portals organized. This prevents the clutter of numerous open tabs, which can be a source of distraction. By keeping digital resources as organized as physical study tools, students can maintain a clear view of their responsibilities and progress, ensuring they remain on track.

Creating Ergonomic and Focused Physical Zones

A physically comfortable space is just as important as a well-equipped digital one. Proper lighting helps reduce eye strain, while an ergonomic chair and a desk adjusted to the correct height support good posture during long study sessions. These physical adjustments ensure that students can remain focused without the distraction of physical discomfort, which is a common barrier to effective learning. A comfortable space also makes it easier to spend more time engaged with challenging materials, as the physical body is supported and not constantly fighting the environment in which the work is taking place.

As families integrate technology across different areas of the home, it can also be useful to consider outdoor setups, such as the approach mentioned in our piece on simple sensors for a busy garden, to create a balanced environment. Applying similar principles of thoughtful arrangement can help maximize the functionality of any space intended for focused work or educational activity. Additionally, keeping the physical surface of the desk clear of non-essential items helps minimize distractions. A clean desk encourages a clear mind, allowing students to focus entirely on their work. Encourage the habit of clearing the workspace after a study session so that it is always prepared for the next time.

Managing Distractions Through Digital Hygiene

Even with the best hardware and organization, digital distractions can still break focus. Managing these effectively is a skill that takes practice but provides lasting benefits. Simple habits can create boundaries between study time and leisure time, allowing the student to fully dedicate their attention to their assignments. These boundaries are crucial for maintaining a healthy balance between the need for deep focus on academic materials and the natural need for relaxation and leisure after a period of intense intellectual activity, which helps prevent burnout and keeps the student motivated.

  • Disable notifications for non-essential applications during dedicated study times to prevent interruptions.
  • Use a separate user profile for academic work to keep personal browsing separate from study materials.
  • Clear open browser tabs and applications that are not needed for the current task to reduce mental clutter.
  • Establish a clear end-of-study routine to help signal that the work period has concluded.

By implementing these small, consistent changes, students can build better habits that carry over to many aspects of their lives. Digital hygiene is less about restriction and more about creating an intentional relationship with the tools being used. This mindful approach helps ensure that technology remains a powerful aid for academic success rather than a source of persistent interruption. Building these skills requires patience and support, but the long-term impact on a student’s ability to maintain focus is significant, helping them achieve their goals with greater ease and clarity.

The goal is to cultivate a space that serves the student’s needs, adapting as their academic requirements evolve. By prioritizing consistency, comfort, and organization, families can create an environment that encourages sustained learning and curiosity, providing a solid foundation for educational success regardless of the subject matter. This effort is a valuable investment in a student’s potential, supporting both academic achievement and the development of life habits that will serve them well.